On September 13, the Financial Times reported that Latham & Watkins has begun buying Nvidia chips and building the infrastructure to run open-weight AI models in-house. This puts Latham a full layer below where the other top-tier legal AI stories have landed: Kirkland & Ellis is working with Palantir. A&O Shearman is deploying Harvey. Freshfields partnered with Anthropic. All three of those are software partnerships, the firm chooses a vendor and sits on top of that vendor’s stack. Latham is doing something structurally different. They are running the stack.
The details that matter to those of us running AI production systems in regulated environments:
Open-weight models. Not proprietary. Downloadable, customizable, self-hosted. The kind of model where the weights themselves are the asset, not access to someone else’s inference endpoint.
Nvidia hardware, in Latham’s own environment. The inference itself never leaves.
The vendor APIs stay. Latham hasn’t stopped using Claude, GPT, or Gemini. This isn’t a “we’re done with the labs” story. It’s a “we now have a choice for the workloads where the labs are the wrong answer” story.
Reported cost: tens of millions of dollars a year. The CIO didn’t frame this as savings. He framed it as strategic optionality.
The sentence that matters, from Latham’s CIO Rene Mendoza: “We are not hitching our wagon to one particular company.”
That is not a technical statement. It is a governance statement, dressed in infrastructure language.
Why this isn’t a “build vs buy” story
Most of the coverage this week has framed Latham’s move as the next round of the build-vs-buy debate. It isn’t. Build-vs-buy asks which vendor do we pick. Latham asked a different question: when we pick, what do we still get to control?
At the software layer, the layer Kirkland, A&O Shearman, and Freshfields are all operating at, the answer is “less than you think.” The vendor owns the model. The vendor owns the inference environment. The vendor owns the roadmap. You own the seat license and the prompt logs.
At the infrastructure layer, the layer Latham just moved to, the answer is “most of it.” You own the model weights. You own the inference environment. You own the audit trail from silicon up. You still don’t own the frontier, the frontier models remain proprietary, and Latham still uses them, but you now have the ability to swap the frontier out for any workload where sending data to a vendor is the wrong call. That is the optionality Mendoza is buying for tens of millions a year.
The build-vs-buy question was being asked at the wrong altitude. The real question, for any CTO in a regulated environment, is where does the trust boundary sit in your stack, and can you move it.
Latham didn’t build a competing model. They bought the ability to choose. That capability, not the hardware, is what your board will ask about by end of quarter.
What actually shifts for regulated-enterprise CTOs this week
Most of us are not going to buy Nvidia chips. That is not the point. Latham has more capital, more technical staff, and more scale-per-workflow than most enterprises. Their playbook does not port directly.
But three things do port, and they should be on every regulated-enterprise CTO’s desk this quarter.
1. Your board just gained a reference point they didn’t have last week. Until this story, the “why are we sending our most sensitive data to a US-based cloud AI vendor” question could be answered with “that’s the industry standard.” It no longer can. A top-tier peer institution just publicly said out loud that for some categories of data, the industry standard is the wrong answer, and they are spending real money to have an alternative. Your risk committee will read the FT piece. Have your answer ready.
2. Model-agnostic architecture stopped being a nice-to-have. If your production stack has one model provider hard-wired into it, SDK calls direct to Claude, or direct to GPT, or direct to Gemini, and switching to a different model provider would take a quarter of engineering work, you are the person Latham’s CIO just described as “hitching their wagon to one particular company.” This is fixable. It is not fixable overnight. Start now. The architectural pattern is straightforward: model providers behind an abstraction, prompts and eval sets as data (not embedded in code), and the ability to route a specific workload to a specific model based on data-sensitivity policy. That last part is where most stacks are still weakest.
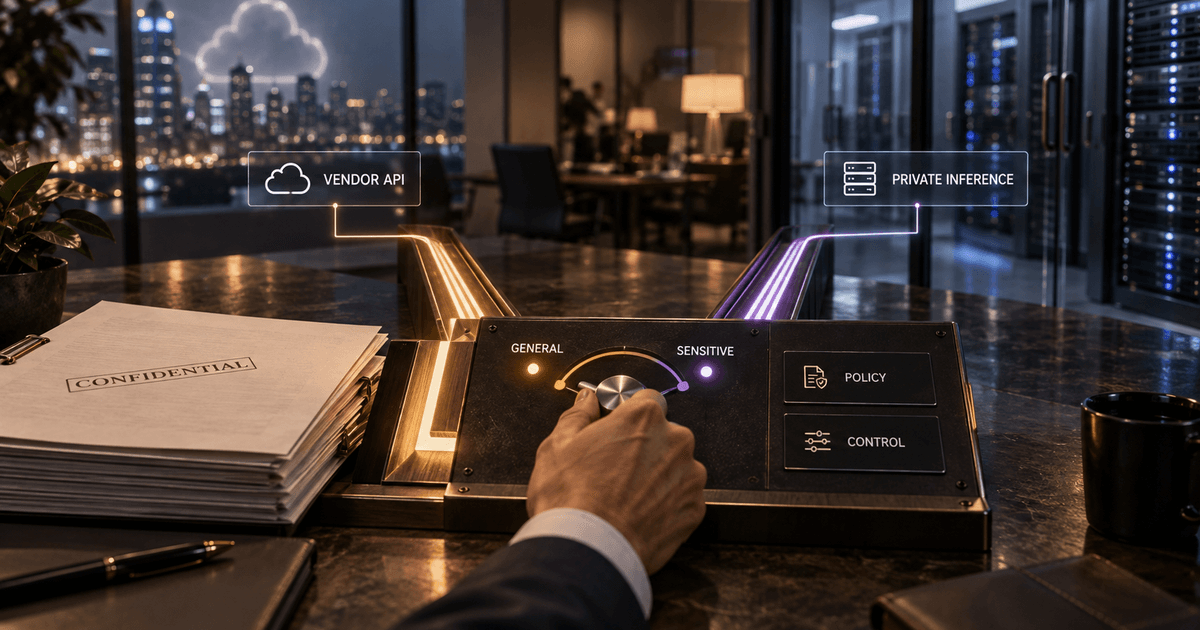
3. “Open-weight, self-hosted” needs to be an option in your architecture, even if you never exercise it. Latham isn’t self-hosting everything. They are self-hosting the workloads where the trust boundary needs to sit inside their own environment. The workload split is what matters. If your architecture cannot support both patterns, frontier-model API for the general workloads, self-hosted open-weight for the sensitive ones, you don’t have a governance problem yet, but you have an architecture problem that will become one. Build the capability to run an open-weight model in your VPC before the compliance officer asks whether you can. The answer “we’d need six months” is a very different conversation from “we have the pattern, we’ve tested it, here’s the workload we’re piloting on it.”
What this does not mean
A few things worth being direct about, because the coverage this week has already started to overshoot:
This is not the end of the frontier labs. Latham still uses Claude, GPT, and Gemini for the workloads where those are the right answer. So should you. The open-weight story is additive, not replacement.
This is not a cost play. Tens of millions of dollars a year is not the cheaper option. Anyone framing this as “bring AI in-house to save on API costs” is reading the wrong story.
This is not portable to every firm. Latham has the capital and the scale to justify it. Most enterprises don’t. What is portable is the architectural readiness to add self-hosted inference to your stack when a specific workload requires it, without a six-month rebuild.
Model-agnostic architecture is what “we are not hitching our wagon to one particular company” actually looks like in code. If your production stack has one model provider hard-wired into it, you are the person the CIO of Latham was describing.
The Builder’s & Operator’s Takeaways
1. Audit your model-provider coupling this week. Grep your codebase. How many production paths have a specific SDK, anthropic.messages.create, openai.chat.completions, google.generativeai, embedded directly in the business logic? Every one of those is a wagon hitch. Wrap them behind an abstraction now. You do not need a heavy framework; you need a routing layer with a policy input and a provider output.
2. Get one open-weight model running in your VPC this quarter. Pick a workload. Ideally a “we would not send this data to a cloud AI vendor” workload, not the flashiest one, the most sensitive one. Prove the pattern end-to-end: model loaded, inference served, logs captured, evals running. Even if you never move a second workload to it, having done it once makes the next conversation a five-minute one instead of a five-month project.
3. Bring the “where does the trust boundary sit” question to your next AI governance review. Not the compliance checklist. The architecture diagram. For each production workload, mark on the diagram exactly where your data crosses out of your control envelope. If the honest answer for a sensitive workload is “when it hits the vendor API,” that is now a documented decision, not an unexamined default. That distinction is the entire audit conversation next year.
The story of the last two years of enterprise AI has been “which vendor do we pick.”
The story of the next two years is going to be “where in our stack are we willing to hand control away, and where do we insist on keeping it.” Latham just made that question concrete, in public, with a spend number attached.
Most regulated-enterprise CTOs will not buy Nvidia chips this quarter. Most probably shouldn’t. But every regulated-enterprise CTO will, by end of the year, be asked some version of the question Rene Mendoza just answered on the record: what data are we willing to send to which vendor, under what governance, and can we move that line when we need to?
The teams that have already built model-agnostic architecture and can run an open-weight model in their own environment when a specific workload requires it will answer that question in fifteen minutes.
The teams that have one vendor SDK hard-wired into the production path will spend the next quarter answering it.
Pick which team you want to be.